Incident management gives teams a repeatable way to detect, assess, contain, resolve, and learn from an unplanned service disruption. Effective response depends on clear severity criteria, accountable roles, escalation paths, communication responsibilities, and access to current runbooks under pressure.
This guide explains the incident management process, how it differs from problem management, the elements of an incident plan, and practical ways to document, test, measure, and improve the response workflow.
What is Incident Management?
Incident management is the structured process for handling an unplanned interruption to a service or a reduction in service quality. Its immediate objective is to limit impact and restore an agreed level of service as quickly and safely as possible. It does not necessarily identify and eliminate the underlying cause; that work may continue through problem management after service is restored.
The term is often used in IT service management, but organizations also maintain related processes for cybersecurity incidents, workplace safety events, business crises, and disasters. These processes can overlap, yet they may have different legal obligations, specialist roles, evidence requirements, recovery objectives, and communication rules. Define the scope of the incident process and connect it to the appropriate security, crisis-management, business-continuity, or disaster-recovery plans.
A typical incident lifecycle includes:
- Detection and logging: Record the incident, source, affected service, time, symptoms, and available evidence.
- Categorization and prioritization: Classify the incident and assign a severity based on impact and urgency.
- Initial diagnosis and assignment: Route the incident to an accountable responder and begin diagnosis using current runbooks and service context.
- Escalation and coordination: Trigger functional or hierarchical escalation when expertise, authority, communication, or additional resources are required.
- Containment, resolution, and recovery: Limit further impact, apply an approved workaround or fix, and restore the service safely.
- Validation and closure: Confirm recovery with affected users or monitoring, document the resolution, and close the operational record.
- Post-incident review: For qualifying incidents, examine contributing factors, response performance, communication, and follow-up work without delaying immediate restoration.
The role of incident management is pivotal for companies, as it directly influences their ability to deliver reliable services. Here’s why incident management is important:
Service continuity: A defined response process can reduce avoidable delay and support restoration priorities during a disruption.
Coordinated resolution: Clear roles, severity criteria, runbooks, and escalation paths help responders organize work and avoid duplicated or conflicting actions.
Clear communication: Timely, accurate updates help employees, customers, and other stakeholders understand the impact, response status, and next expected update.
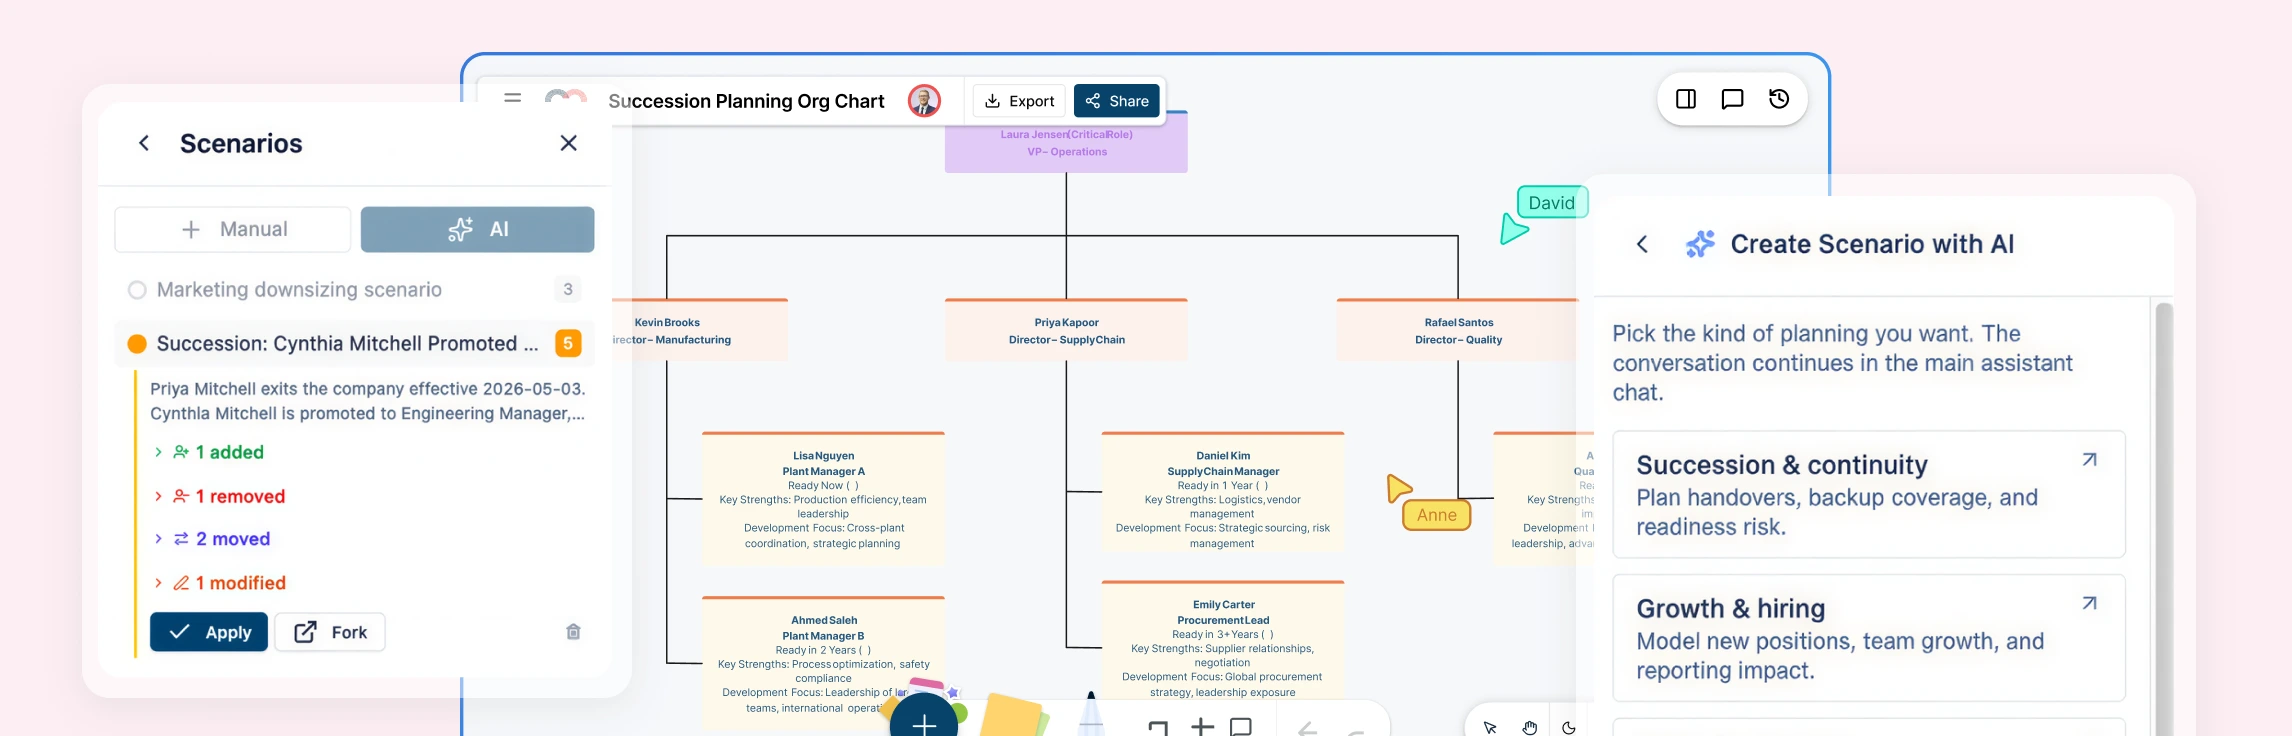
An incident-management platform or service desk normally records and coordinates live incident activity. A process map complements that system by documenting the expected workflow, roles, escalation logic, and connected runbook context used to prepare and train responders.


Incident Management vs. Problem Management
Incident management focuses on restoring service and reducing immediate impact. Responders may use a workaround without knowing the root cause if that is the safest and fastest way to recover the service.
Problem management investigates underlying or potential causes, maintains known errors and workarounds, and coordinates changes intended to reduce recurrence or impact. It can be reactive after one or more incidents or proactive when trends and risks reveal a problem before a major disruption occurs.
| Incident Management | Problem Management |
|---|---|
| Restores an agreed service level as quickly and safely as possible | Investigates actual or potential causes |
| Prioritizes immediate impact and urgency | Prioritizes recurrence, risk, and long-term service health |
| May implement a workaround before the root cause is known | Documents known errors and coordinates permanent corrective work |
The processes should exchange context without becoming the same workflow. Incident records provide evidence for problem analysis, while known errors and workarounds from problem management can help incident responders restore service faster.
Advantages of Implementing Incident Management Processes
The value of incident management should be evaluated through measurable operational and stakeholder outcomes rather than assumed. Relevant benefits may include:
- Reduced restoration delay: Defined routing, escalation, and response roles can reduce time lost during triage and coordination.
- Consistent communication: Predefined audiences, channels, owners, and update intervals help teams communicate verified information without creating conflicting messages.
- Operational learning: Incident data and post-incident reviews can reveal gaps in monitoring, runbooks, ownership, architecture, training, or communication. Corrective work should be tracked in the appropriate system rather than assumed to prevent recurrence automatically.
Types of Incident Management
Reactive Incident Management
Reactive incident management begins after an incident is reported by a user or detected by monitoring. The team logs, categorizes, prioritizes, assigns, diagnoses, escalates, resolves, validates, and closes the incident according to the defined process.
Proactive Incident Management
The phrase “proactive incident management” is sometimes used for monitoring, preparedness, and preventive work, but root-cause analysis and recurrence reduction are generally associated with problem management, change management, reliability engineering, security, or continuity planning. Keep ownership clear so preventive work does not disappear between processes.
Major Incident Management
Major incident management is an accelerated path for incidents that meet predefined high-impact or high-urgency criteria. It commonly introduces an incident commander or major-incident manager, dedicated technical and communication roles, a coordination channel, frequent status updates, executive escalation, and a formal post-incident review. Declare and stand down a major incident using documented authority and criteria.
Continuous Improvement Incident Management
Continuous improvement is not a separate incident type. It is the practice of reviewing incident data, responder feedback, post-incident findings, exercises, and process metrics to improve the response system. The process owner should prioritize agreed changes, update the documented workflow and runbooks, communicate the active version, and verify whether the change improved response performance.
Elements of an Incident Management Plan
Now that you have an understanding of what an incident management plan is and why it is important, let’s dive right into formulating one for your organization. A good incident management plan should contain the following elements.

1. Risk Assessment
Preparedness begins by identifying credible service disruptions, dependencies, and response constraints. Use a risk assessment process and a risk probability and impact matrix where appropriate. Cybersecurity events, natural hazards, supplier failures, infrastructure outages, and reputational crises may require related specialist plans rather than one generic incident procedure.
A business impact analysis (BIA) examines how disruption affects critical activities over time and helps establish recovery priorities and objectives. Depending on scope, consider effects on:
- Customer experience
- Business reputation
- Loss of income
- Cost increments
- Legal implications
Creately allows you to:
- Map the preparedness workflow and use visual risk-assessment or impact-analysis templates to organize stakeholder input.
- Use real-time editing, live cursors, and threaded comments to review the documented plan together.
2. Determine the Actions
Define the detection sources, activation triggers, severity criteria, initial response actions, escalation thresholds, communication cadence, and conditions for recovery and closure. Create separate branches or linked subprocesses when different incident categories require specialist responders or regulatory procedures.
Creately allows you to:
- Map the incident workflow and related operating procedures with customizable flowchart or process-map templates.
- Attach links, documents, images, notes, and system details to the relevant process steps so responders can access supporting context without cluttering the incident flow.
3. Assign Roles and Responsibilities
Assign operational roles before an incident occurs. Depending on scope, these may include an incident commander, technical lead, communications lead, service owner, security or legal specialist, business liaison, and scribe. A roles and responsibilities matrix (RACI) can clarify preparedness and process ownership, while the live response should use an explicit command structure and designated incident system.
Creately allows you to:
- Get a head start on the assignment of responsibilities with readymade and customizable RACI matrix templates.
- Record owners, roles, status, duration, systems, and other structured details on the relevant incident-response steps.
4. Have a Clear Cut Communication Strategy
Define an incident communication strategy covering internal and external audiences, authorized communicators, approval requirements, channels, update frequency, severity-based templates, accessibility, and legal or regulatory obligations. Communicate confirmed facts, known impact, response status, workarounds, and the next expected update without speculating about an unverified cause.
Keep role-based contact and escalation information current, secure, and available through the designated incident system or authoritative directory. Test the communication path during exercises rather than discovering missing access during a live incident.
Creately allows you to:
- Connect role descriptions, escalation references, communication templates, and links to authoritative contact information to the relevant process steps.
5. Review and Update the Plan As Needed
Review the plan with responders, service owners, communications, security, legal, continuity, and other relevant stakeholders. Exercise likely scenarios to test decision points, access, handoffs, escalation, and communication. After an incident or exercise, record feedback, have the accountable process owner incorporate agreed changes, and communicate the active version.
Creately allows you to:
- Share the relevant workspace with appropriate view or edit access.
- Use threaded comments and @mentions to collect feedback on the documented workflow without implying formal approval states.
- Edit the process synchronously with distributed stakeholders.
- Export your workspace in JPEG, PNG, PDF and SVG formats to be embedded in presentations, reports, other sites or intranets.
Best Practices for Managing Incidents
Incident management should be reviewed as an operational system, not only after a major failure. Useful practices include:
- Severity and escalation rules: Define impact and urgency criteria, authority to declare a major incident, response targets, and functional or hierarchical escalation paths.
- Blameless post-incident reviews: Examine system conditions, decisions, communication, and contributing factors. Assign follow-up work in the appropriate action-tracking system with an owner and due date.
- Exercises and training: Test realistic scenarios, unavailable responders, failed communication channels, and manual fallback procedures. Update training and runbooks from observed gaps.
- Metrics and KPIs: Track measures such as detection time, acknowledgement time, restoration time, time at each handoff, escalation delay, recurrence, reopen rate, SLA attainment, and communication timeliness. Interpret metrics by severity and service context rather than using one average alone.
- Living process documentation: Review the map on a risk-based cadence and after material changes. Stakeholders provide comments, the process owner incorporates agreed updates, and teams are directed to the active version.
Conclusion
An effective incident management process defines how teams detect, prioritize, assign, escalate, resolve, communicate, validate, close, and learn from service disruptions. It should connect to—not replace—security response, problem management, change management, business continuity, crisis management, and disaster recovery where those processes apply.
Creately’s process mapping software can visualize the response flow, document process ownership and escalation paths, and keep runbook links, files, notes, systems, status, and related subprocesses connected to relevant steps. Real-time collaboration and threaded comments support review of the documented process. Live incident execution, alerts, ticket records, formal approvals, and corrective-action tracking remain in the organization’s designated systems.